Open to engineering roles & contract work

Ndemafia Wilsmith

Software Engineer · Document AI & Data Pipelines · Cybersecurity Research

I build pipelines that turn scanned documents into data people can trust: OCR at scale, vector search, and LLM workflows designed to fail loudly instead of silently. I also find access control flaws in production systems and report them privately.

By the numbers

Measured, not estimated

31,887

scanned textbook pages turned into searchable, cited data

55,106

exam questions in the production corpus my pipeline feeds

140K+

vectors served from PostgreSQL with pgvector

3

access control flaws found and reported privately

48 h

for ngCERT to validate my Corporate Affairs Commission report

1

production website built and deployed as sole developer

Case studies

Systems where the hard part was everything around the happy path

Document AI, data pipelines and ML infrastructure I built and run in production, with the bugs, rejected designs and measurements included.

DOCUMENT AI · OCRPrivate repo

Printed page citations from image-only scans

Recovering the printed page number for 83,807 textbook sections after OCR had discarded page positions and the PDFs turned out to have no text layer.

99.3%
sections with a page citation
93 of 102
books citing printed page numbers
  • Python
  • AWS Bedrock
  • +5 more
Read the case study
APPLIED AI · VECTOR SEARCHView repo

Prep50 Coverage

Semantic duplicate detection and exam forecasting over a ~40,000-question WAEC archive.

~40K
questions indexed
~2 min
verdict per paper
  • Python
  • FastAPI
  • +9 more
Read the case study
DATA ENGINEERING · DOCUMENT AIPrivate repo

From exam paper to vector index

A six-stage pipeline turning two decades of WAEC and JAMB papers, from printed booklets to screenshots to inconsistent Word documents, into a classified, queryable corpus.

55,106
questions in production
11,000+
extracted and verified
  • Python
  • GPT-4o vision
  • +9 more
Read the case study
ML INFRASTRUCTURE · AWSPrivate repo

Textbook digitization pipeline

An event-driven GPU pipeline turning 102 scanned curriculum textbooks into clean, structured Markdown, unattended, recovering from the failure modes of open-source ML inference at scale.

102
textbooks digitized
31,887
pages processed
  • Python
  • Bash
  • +10 more
Read the case study
Web

A production site, built and deployed alone

B-Lord Group

blordgroup.ng

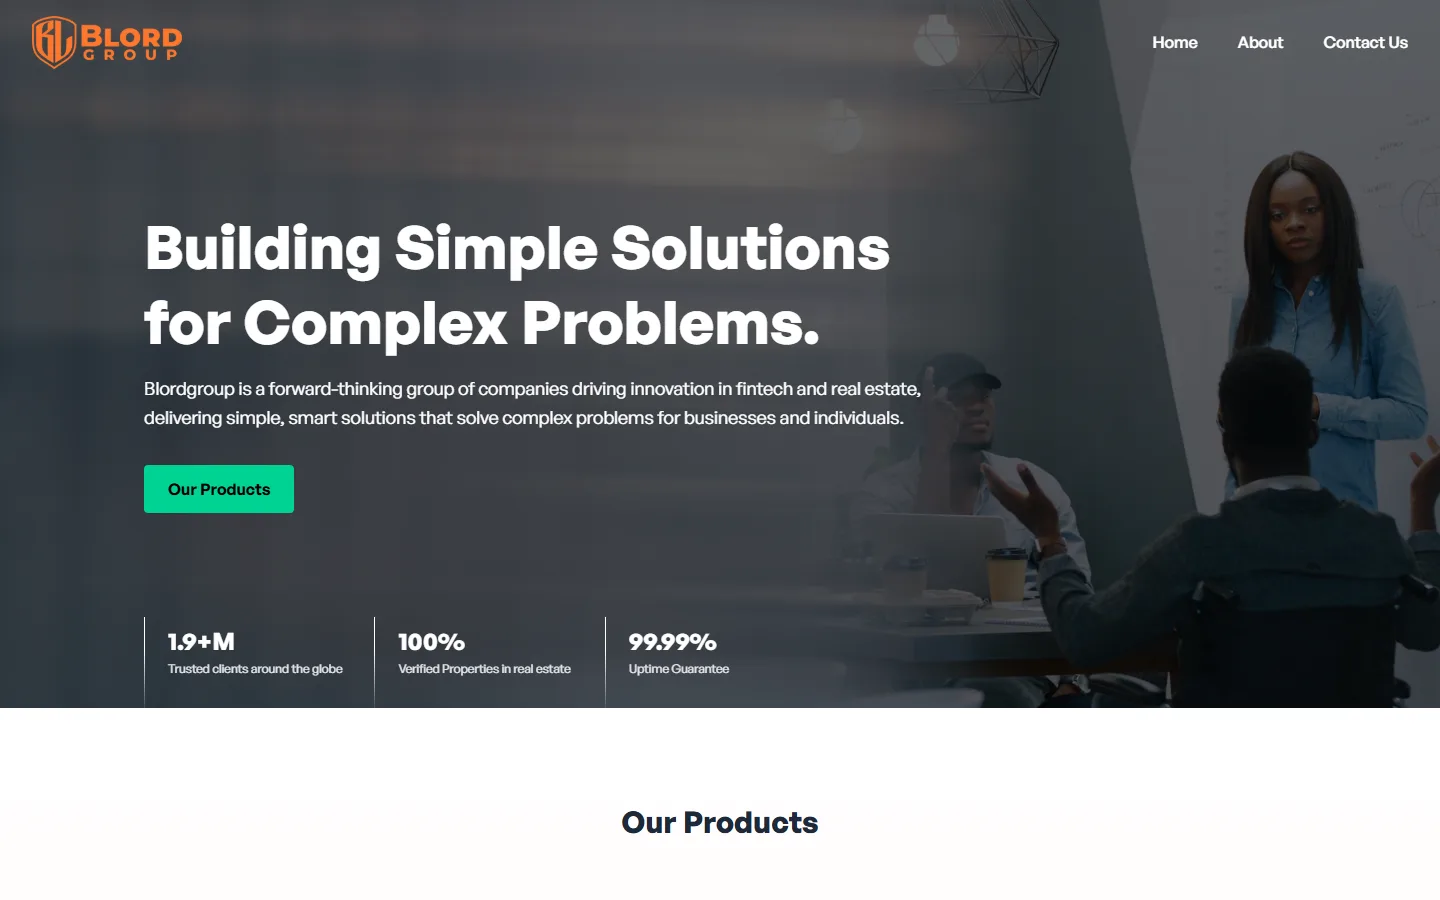
The group’s official website, which I built and deployed as sole developer. It runs on Next.js behind Nginx on an Ubuntu server, and it was built for phones first because most visitors arrive on slow mobile connections.

The blordgroup.ng home page on a desktop browser.
  • Next.js
  • React
  • Nginx
  • Ubuntu
  • Mobile first
Get in touch

Hiring, or working on a hard data problem?

I am open to engineering roles and contract work in document AI, data pipelines and web. Vulnerability reports go to the security address.